<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://efp.asia/feed.xml" rel="self" type="application/atom+xml" /><link href="https://efp.asia/" rel="alternate" type="text/html" /><updated>2026-10-16T16:13:31+00:00</updated><id>https://efp.asia/feed.xml</id><title type="html">efpasia</title><subtitle>thinking about something</subtitle><author><name>text me if you want efpasia@gmail.com</name></author><entry><title type="html">Code Is a Commodity Now</title><link href="https://efp.asia/blog/2026/10/15/code-is-a-commodity-now/" rel="alternate" type="text/html" title="Code Is a Commodity Now" /><published>2026-10-15T04:00:00+00:00</published><updated>2026-10-15T04:00:00+00:00</updated><id>https://efp.asia/blog/2026/10/15/code-is-a-commodity-now</id><content type="html" xml:base="https://efp.asia/blog/2026/10/15/code-is-a-commodity-now/"><![CDATA[<h2 id="the-numbers-first">The numbers first</h2>

<p>On <a href="https://djinni.co/">Djinni</a>, Ukraine’s largest tech job board, frontend fell from 5.1% of all vacancies in January 2025 to 1.6% in August 2026 (DOU trends). Applications per frontend listing went from 59 in March to 112 in September. Developers as a whole went from 67% of all hires a decade ago to 36% now.</p>

<p>The easy objection is that this is one wartime market. Fine, but the same curve shows up in markets with no war in them. <a href="https://www.hiringlab.org/">Indeed Hiring Lab</a>’s index of US software-development postings sits roughly 70% below its 2022 peak and about a quarter below pre-COVID levels. Of the past year’s modest rebound, 71% came from senior roles. The junior end is worse: a Stanford analysis of ADP payroll data found employment of US software developers aged 22 to 25 down about 20% since late 2022, while older engineers in the same roles grew. That’s the demand side. On the supply side, Sundar Pichai said in April that <a href="https://www.semafor.com/article/04/24/2026/google-ceo-says-75-of-companys-new-code-is-ai-generated">75% of Google’s new code is AI-generated</a>. It was 25% in 2024 and 50% last fall.</p>

<p>More and more prospects ask for teams of one to three people: one person who designs and ships the frontend, one who handles the backend, DevOps, and everything else. The classic setup with separate designers, frontend and backend developers is, as they put it, a legacy org chart. “That’s the default now,” they say.</p>

<p>If you came for the “AI replaces everyone” post, or the “AI hacks everything” one, this isn’t it. I have little patience for either camp. The closest economic rhyme I can find is the US railroad build-out: wildly overhyped in its moment, capex running far ahead of real revenue, priced almost entirely on projections of future profit. Many railroads went bust, and the economy still got rewired on the tracks they left behind. That’s roughly where AI is now. Megacap spending isn’t backed by current revenue, the promised GDP miracle is nowhere in the data yet, and the structural shift is happening anyway. The development market is changing shape rather than emptying out. But I’m getting sidetracked - that’s a topic for another post.</p>

<p>So this is the colder read: the cost of producing working software is deflating, and everything priced on top of that cost will reprice. I want to trace where the margin goes, because I think the direction is a lot more visible than most of the market admits.</p>

<hr />

<h2 id="the-mechanism">The mechanism</h2>

<p>Commoditization follows a script old enough to trust, and open source is the version everyone in software has lived through. In the mid-1990s Netscape sold web servers for real money. Within a few years Apache was free, and Microsoft was giving IIS away with Windows, and the business of selling a web server had all but vanished. The money didn’t disappear, though. It moved to the companies that would run those servers for people who didn’t want to run them themselves, first hosting firms, then the cloud.</p>

<p>Code entered this script a while ago; what’s new is the speed. Google went from 25% of its new code being generated to 75% in about eighteen months. That is a cost curve, whatever Pichai meant it as. One of the largest engineering organizations on earth now ships the machine-written line three times out of four, so a line of working code costs Google a fraction of what it did in 2024, and what it costs Google is what it costs everyone a few years later. You can already see it on sales calls: the client shows up with a Lovable prototype that runs, and the quote has to explain why finishing it costs more than the subscription that produced it. “We build well, fast, and cheaper than before” stops being a pitch at that point. The client assumed it before they emailed.</p>

<hr />

<h2 id="what-this-does-to-the-services-market">What this does to the services market</h2>

<p>A service business sells intangible value: time, specialized knowledge, labor, convenience. It exists to relieve a pain the client can’t or won’t handle themselves. For twenty years, “we can build software” qualified, because building was scarce. So the industry priced the scarce part: dev hours.</p>

<p>That pricing basis is now deflating from three directions at once. Customer acquisition costs keep rising across outsourcing. Engagements run shorter because clients expect faster time-to-market. And the deliverable itself is sliding into the commodity column: when a client can get a product running on a $200/month subscription and a handful of SaaS platforms, there is no financial reason to pay a team for the build. No sales process fixes that, because the pain the whole business was built to relieve is going away.</p>

<p>A commoditizing service earns less margin per unit of itself, permanently. That leaves two strategies I’d take seriously:</p>

<p><strong>Volume:</strong> keep selling default development, accept the shrinking margin, and win on predictably cheap customer acquisition at scale. This is a real business, just a different one, closer to hosting than consulting. Most agencies have neither the sales machine nor the cost structure for it, and they’d be up against large offshore development firms that have spent decades industrializing exactly this kind of work. Competing with them on price is like a small Western workshop trying to beat contract manufacturers on unit cost.</p>

<p><strong>Reposition:</strong> move sideways into what a client cannot get from a subscription: knowing their domain better than they expected you to, telling them which half of the spec not to build, design a founder can’t get from a template, owning the outcome and eating the risk when it doesn’t land. Trust most of all. When anyone can generate code, someone still has to put their name under “this is correct, this is safe, this was worth building,” and that signature is the slowest thing in this industry to commoditize. The deliverable shifts from “the application” to “the decision and the result,” and pricing, as expected, follows it.</p>

<hr />

<h2 id="the-regulated-market-trap">The regulated-market trap</h2>

<p>There’s a third option that looks pretty attractive at first: take shelter in regulated industries. Think MedTech, FinTech, InsurTech, RegTech, GovTech, PropTech, LegalTech—you know, all the “-Tech”s with compliance headaches. The logic makes sense: regulations slow things down, so the wave of commoditization reaches these sectors a little later. But that’s just it—later, not never. In my experience, these industries generally run about two years behind the wider market, and then the same trends catch up. Regulation (or governments, since GovTech is always slowest) might drag out the timeline, but it doesn’t change where things are headed. So sure, jumping into a regulated vertical could buy you some breathing room to rethink your game plan, but if you treat it as your main strategy, all you’re really doing is postponing the same challenge until 2028.</p>

<hr />

<h2 id="where-id-argue-against-myself">Where I’d argue against myself</h2>

<p>The productivity story isn’t clean, and I’d be cheating if I pretended otherwise. <a href="https://metr.org/">METR</a> ran a randomized trial last year: experienced open-source developers using early-2025 tools were 19% slower in their own repos, and believed they were faster the whole time. Google’s DORA 2025 survey has over 80% of developers saying they feel more productive. I don’t think either side is lying. What I see fits the trial: on a greenfield project or a pile of boilerplate, the tools are absurdly good, and inside a dense ten-year-old codebase they produce plausible code that takes longer to check than it would have taken to write. But a good harness around the project changes the picture. <a href="https://clickhouse.com/blog/agentic-coding">ClickHouse</a> gets wonderful results that way, and the tools keep evolving and getting more polished.</p>

<p>The other thing the doom reading misses is Jevons paradox: cheap inputs expand consumption. Every SMB that could never afford custom software, internal tools for teams of five, vertical micro-products in industries consultants ignore, software with exactly one user. The market for writing code deflates while the software market grows by an order of magnitude, both at the same time. That’s why I care less about whether there will be less work than about who captures the new shape of it.</p>

<hr />

<h2 id="the-trends-to-watch">The trends to watch</h2>

<p><strong>Role consolidation.</strong> The “frontend developer” listing is turning into a “design engineer” or “product engineer” listing: one person with taste who ships, with agents doing the typing. <a href="https://vercel.com/blog/design-engineering-at-vercel">Vercel has a whole team under that title</a>, Cursor’s new Head of Design is hiring for it, and it keeps showing up in Anthropic, Stripe, and Lovable postings.</p>

<p><strong>Pricing migration.</strong> From hours toward fixed, outcome, and value pricing. Billing fixed while delivering with AI is real margin today, but every competitor will be doing it within a couple of years, so it’s rather an arbitrage opportunity than a real strategy.</p>

<p><strong>Team compression.</strong> The one-to-three-person team from the top of this post is where this ends up: small generalist teams running agents ship what took eight to ten people in 2023, so each project needs fewer people, and each person carries more projects. Indeed’s senior-heavy rebound fits that picture.</p>

<p><strong>The junior squeeze.</strong> Newcomers feel it most. The entry bar was already high, with a crowded pool of fresh graduates competing for the same junior roles, and it’s rising further as most of the market sees little reason to pay for a junior’s ramp-up. The entry point probably won’t disappear so much as get renamed: fewer “junior developer” postings, more roles built around orchestrating agents, whatever title sticks.</p>

<p><strong>Verification as a market.</strong> AI-code audit, security review, accountability. High margin while it’s a practice, and a feature once someone turns it into tooling (What is the prospect for this?).</p>

<p><strong>The spec displacing the codebase as the asset.</strong> Code as build output that gets regenerated more and maintained less. This is the furthest out of the six and the hardest to put a date on, but I find it the hardest to argue against directionally.</p>

<hr />

<h2 id="the-knock-on-effects">The knock-on effects</h2>

<p>A few second- and third-order effects I’d expect, held with less confidence than the trends above.</p>

<p><strong>Build beats buy again.</strong> For twenty years, the default advice was to buy because building was the expensive option, and now it flips. The long-tail SaaS dies because the customer’s IT team rebuilds it in a week, with exactly the fields they need and none of the ones they don’t. Corporate IT turns back into a software producer, the way the mainframe shops of the 80s were before packaged software turned it into a procurement department (btw I had some really nice old article about mainframe developers and they are also good addition and comparison for AI in development, I’ll attach it if I find). The first casualties are the products that are priced on lock-in rather than on anything you couldn’t rebuild. People are already vibe-coding Photoshop clones for their own use. A subscription whose main retention tool is the pain of canceling and migration costs (Adobe’s, say) is in more trouble than one sitting on data, a network, or a compliance stamp.</p>

<p><strong>Hiring signals go blind.</strong> Every signal the industry uses to hire measures typing and language knowledge. GitHub contribution graphs, LeetCode, years of experience, the live-coding round: all of them test whether a person can produce working code under time pressure, and that is the thing that just became cheap. Nobody has a good test yet for what is now scarce. Can they catch the bug the agent didn’t? Can they run four tasks in parallel without losing their minds? Do they think in product, or do they wait for a detailed ticket? Can they tell a client “don’t build this” and be right? I don’t know what that interview looks like. Probably something closer to a design review than a whiteboard: like here is a messy repo, here is an agent, here is a vague ticket from a real client, show me what you ask before you start.</p>

<p>Put three things together: someone has to carry liability for generated code, seniors are getting scarce, and nobody can tell from a CV who is good. That combination is what produced CPAs and the PE license for engineers. I’d expect a licensed engineer’s sign-off to become a legal requirement in a few verticals first (medical devices, finance, anything a government buys), then spread.</p>

<p><strong>Drag-and-drop no-code dies.</strong> No-code was a workaround for expensive code. Bubble, Adalo, the long tail of visual app builders: all of them let a non-programmer get software without paying a programmer, at the price of living inside someone else’s box. When the programmer costs $200 a month and speaks English, nobody needs the box. The visual tools that survive are the ones that were never really about avoiding code. The ones whose whole pitch was “you don’t need a developer” discover that the customer no longer needs them either.</p>

<p><strong>The technical co-founder stops being a requirement.</strong> For fifteen years the first question an investor asked a non-technical founder was “who’s building it?” and that question is losing its teeth. A founder with a domain and a customer list can get to a working product without a CTO, which means seed money stops funding the build and starts funding distribution: sales, content, channels, whatever gets the thing in front of buyers. Therefore rounds get smaller, because there is less to build before revenue. So we get more companies (?) with less seeding money. Which is the services-market conclusion one layer up: the build is no longer where the money gets decided.</p>

<hr />

<h2 id="where-it-goes">Where it goes</h2>

<p>I don’t know where this ends, and anyone selling certainty about 2030 is selling something. What the past does show is where the money tends to go. The railroads were overbuilt, and plenty of the companies that laid the track went under. The fortunes went to whoever used the rails to move something people needed: steel, cattle. The value went to the layer on top. My list of what stays scarce is judgment, distribution, accountability, and taste. If I had to bet, I’d bet on distribution and accountability, because they depend on other people (customers, courts, insurers) rather than on how good the models get. Judgment and taste are the two I’d watch for the same treatment code just got.</p>

<p>For the services market specifically, the question itself has already moved. It used to be “can you build it?” It’s becoming “what should exist, and who owns the result?” The companies repositioning around that question get to discover the new margin structure firsthand. The ones waiting for 2021 to come back are already visible in the numbers up top: they’re the declining line, and they’re shutting down.</p>]]></content><author><name>efpasia</name></author><category term="thoughts" /><summary type="html"><![CDATA[The numbers first]]></summary></entry><entry><title type="html">Not All Code Architectures Survive the Agent</title><link href="https://efp.asia/blog/2026/04/05/agentic-coding-architectures/" rel="alternate" type="text/html" title="Not All Code Architectures Survive the Agent" /><published>2026-04-05T15:00:00+00:00</published><updated>2026-04-05T15:00:00+00:00</updated><id>https://efp.asia/blog/2026/04/05/agentic-coding-architectures</id><content type="html" xml:base="https://efp.asia/blog/2026/04/05/agentic-coding-architectures/"><![CDATA[<p>Most of the debate around agentic coding is about tooling – which IDE, which model, which CLI to use, and so on. Much less attention goes to a more interesting question: <em>does the way we’ve been taught to structure code even make sense</em> when the thing writing it has limited long-term memory, a finite context window, and often has to make progress without holding the whole system in view?</p>

<p>This is an analysis of different code architectures – TDD, OOP, FP, MVC, MVVM, microservices, event-driven, CQRS, hexagonal, BDD, DDD – sorted by how well they actually work when an agent is doing the coding.</p>

<hr />

<h2 id="four-properties-that-actually-matter">Four Properties That Actually Matter</h2>

<p>Before ranking anything, we need to define what <strong>agent-friendly</strong> even means. After enough sessions working with agents and thinking about this, I’ve landed on four properties that explain most outcomes.</p>

<h3 id="can-the-agent-reason-about-a-piece-of-code-locally">Can the agent reason about a piece of code locally?</h3>

<p>A pure function that takes inputs and returns outputs can be verified by looking at it. An event handler that depends on twelve other subscribers firing in the correct order requires understanding the whole system. Current agents generally perform much better at <strong>local reasoning</strong> and degrade under <strong>global reasoning</strong>, because the context window is finite and everything outside it might as well not exist.</p>

<h3 id="can-the-agent-verify-its-own-work-mechanically">Can the agent verify its own work mechanically?</h3>

<p>TDD gives you a binary green/red signal. OOP done “well” requires the kind of taste that comes from years of reading and writing code – when to inherit vs compose, how deep to go with the hierarchy, what level of abstraction is appropriate, and so on. Agents don’t reliably exercise that kind of design judgment because they have pattern-matching across training data, and the training data is full of terrible OOP.</p>

<h3 id="is-control-flow-explicit-or-implicit">Is control flow explicit or implicit?</h3>

<p>MVC is explicit – a request hits a route, controller calls a service, service returns data. Event-driven is implicit – an event is published, and somewhere else something handles it, and the only way to know what that something is is to search every file for subscribers. Agents can follow explicit flow like a recipe. Implicit flow tends to degrade agent performance for the same reason it frustrates junior developers: too much important behavior is off-screen.</p>

<h3 id="whats-the-ratio-of-actual-logic-to-boilerplate">What’s the ratio of actual logic to boilerplate?</h3>

<p>A functional pipeline is almost pure signal. A full DDD implementation with aggregates, value objects, domain events, repositories, and bounded contexts can be 80% ceremony before you’ve written a line of meaningful logic. High ceremony raises the cost of getting changes right under limited context – every scaffolding line is a line where the agent can introduce a subtle bug, and a line that eats context window for no value.</p>

<p>Every paradigm scores differently on these four, and the ones that score well across all four are the ones that make agents genuinely good.</p>

<hr />

<h2 id="s-tier-best-of-them-all">S-Tier: Best of Them All</h2>

<h3 id="tdd">TDD</h3>

<p>This is the one. If you take nothing else from this post: <strong>use TDD with your coding agents.</strong></p>

<p>An agent’s core weakness is epistemic – it generates code that looks correct but has no mechanism to know it’s actually correct. TDD converts the problem from random data generation of the most common outcomes to an iterative process. Write a test (which is just restating the spec in executable form), run it, see red, write the smallest implementation that passes, see green. The agent gets a specific mechanical signal at every step.</p>

<p>The only problem with this approach is the difficulty of zero-shot doing large problems; in these cases, agents tend to “hack” the tests. This is a strong signal of either a lack of context or the task’s high complexity, suggesting the agent, for some reason, can’t complete it.</p>

<p>But the real killer feature is that <strong>the test suite is externalized memory</strong>. An agent has zero recall of what it built three sessions ago. The tests from those sessions still exist and still run. Every new change runs against every existing test. The agent gets automatic regression detection for code it has no memory of writing.</p>

<p>TDD also creates something I’d call <strong>confident composability</strong>. The agent can build function B on top of function A without re-reading A’s implementation, because A’s tests guarantee its contract. As long as those tests pass, A works. The agent only needs to know A’s interface, not its internals. This property scales – the bigger the project gets, the more TDD helps, which is the opposite of most paradigms for agents.</p>

<p>Local reasoning ✓, mechanical verification ✓, explicit flow ✓, high signal ratio ✓. Four for four.</p>

<h3 id="functional-programming">Functional Programming</h3>

<p>Pure functions have a property that’s almost uniquely valuable for agents: <strong>local correctness becomes much more meaningful when there’s no hidden state.</strong> If <code class="language-plaintext highlighter-rouge">transformOrder(order)</code> returns the right output for the right inputs, you’re done with that function. There’s no shared variable that some other function mutated underneath you, no spooky action or trigger at a distance. The agent doesn’t need to hold the entire codebase in context to verify one piece of it.</p>

<p>Immutability eliminates an entire class of bugs that agents are particularly bad at catching – like when function A modifies a shared variable, and function B reads it later assuming it’s unchanged. These bugs are invisible in the code of both A and B individually. You can only see them by understanding the system globally, which agents often struggle to do.</p>

<p><code class="language-plaintext highlighter-rouge">parse → validate → transform → save</code> is also readable for agents. Each step is independently testable. The agent can work one function at a time, test it, and move on with confidence that nothing it did earlier will break.</p>

<p>The practical caveat: purely functional style doesn’t map onto every problem domain. Obviously, you need IO, you need state, you need side effects somewhere. The trick is to push FP as far as it goes – pure domain logic, immutable data transforms, composition pipelines – and contain the impure parts at the edges.</p>

<h3 id="bdd">BDD</h3>

<blockquote>
  <p>“Given a user with an expired subscription, When they try to access premium content, Then they should see an upgrade prompt.”</p>
</blockquote>

<p>That’s a prompt. <em>That is a prompt.</em> The translation from Gherkin to implementation is almost mechanical, and it’s exactly the kind of structured natural language → code task that LLMs were built for.</p>

<p>But BDD does something more important: it pushes the spec to be unambiguous before coding begins. The biggest source of agent errors is underspecified requirements and a lack of context. When the agent has to decide “what should happen when the user submits an empty form?” on its own, it guesses. BDD reduces this class of problems by requiring concrete scenarios.</p>

<p>The combination of <strong>BDD specs and TDD execution</strong> is the highest-leverage setup for agentic coding on new projects I’ve found.</p>

<hr />

<h2 id="a-tier-strong-fits-with-minor-friction">A-Tier: Strong Fits with Minor Friction</h2>

<h3 id="hexagonal-architecture-ports--adapters">Hexagonal Architecture (Ports &amp; Adapters)</h3>

<p>The core rule: <strong>all dependencies flow inward</strong> through defined interfaces. Domain logic has zero knowledge of databases, HTTP, or file systems. This means the agent can write the domain layer as pure functions – S-tier territory – and then wire up adapters independently.</p>

<p>Each adapter is a self-contained unit. Writing the PostgreSQL adapter requires knowing the port interface and knowing PostgreSQL. It doesn’t require understanding the HTTP adapter, the domain logic, or any other adapter. The agent’s context window only needs to hold the port interface and the specific technology it’s adapting to.</p>

<p>The friction keeping it from S-tier: the agent needs to understand the architecture upfront. If you don’t tell it “we’re using hexagonal architecture, the domain logic is in <code class="language-plaintext highlighter-rouge">/core</code>, ports are interfaces in <code class="language-plaintext highlighter-rouge">/ports</code>, adapters implement those interfaces in <code class="language-plaintext highlighter-rouge">/adapters</code>,” it will cheerfully mix database queries into your domain logic. A good <code class="language-plaintext highlighter-rouge">CLAUDE.md</code> or system prompt makes this much easier to enforce.</p>

<h3 id="mvc">MVC</h3>

<p>MVC becomes A-tier not due to its theoretical excellence, but rather due to the <strong>massive volume of available training data</strong>. All tutorials for frameworks, all answers to questions posted at Stack Overflow, and all bootcamp projects use MVC. As such, AI agents have been exposed to more MVC code than any human would be able to read in their lifetime.</p>

<p>The MVC pattern is mechanical and predictable enough that AI agents are reliable in following this pattern. The route exists somewhere within the structure (i.e., wherever you tell them), the controller will call the service, the service will interact with the model, and finally the view will render the response back to the user.</p>

<p>While MVC has less of a ceiling <strong>than</strong> Hexagonal Architecture – as MVC does allow business logic to reside within controllers when it should exist elsewhere – agents generally do a better job at navigating MVC compared to other patterns that may include an abstraction layer or more layers of indirection. Agents understand where things are. While the code generated by this process is rarely beautiful, it works well and is easily debugged. Any developer on your team will also be able to understand how to navigate this code without needing to reference information that was provided during a previous session.</p>

<p>As a result, if speed is most important for greenfield projects, using an agent to implement MVC is one of the best bets possible.</p>

<hr />

<h2 id="b-tier-useful-but-with-real-trade-offs">B-Tier: Useful But With Real Trade-offs</h2>

<h3 id="cqrs">CQRS</h3>

<p>CQRS has a clean conceptual separation: reads and writes use different models. The agent can follow this mechanically – command handlers go here, query handlers go here, never mix them.</p>

<p>The problem is that for a new project built zero-shot, CQRS is almost always premature. You’re doubling your surface area – two models, two pathways, synchronization between them – for benefits that often materialize under load patterns most new projects won’t see for months. An agent will faithfully implement the full CQRS machinery if you ask for it. It’ll produce a technically correct implementation that’s far more complex than what the project needs at that stage, eating context window and creating more surface area for bugs.</p>

<p>Good pattern. Rarely the right default for greenfield agentic development.</p>

<h3 id="oop">OOP</h3>

<p>Simple OOP – data classes, shallow composition, encapsulation – is perfectly fine for agents. A <code class="language-plaintext highlighter-rouge">User</code> class with properties and a couple of methods is trivially correct.</p>

<p>The problem is that <strong>OOP done well requires design judgment</strong>, and that’s the one thing agents don’t reliably exercise. When do you inherit vs compose? How deep should the hierarchy go? Is a <code class="language-plaintext highlighter-rouge">UserService</code> the right abstraction, or should it be <code class="language-plaintext highlighter-rouge">AuthenticationService</code> and <code class="language-plaintext highlighter-rouge">ProfileService</code>? These are judgment calls where the right answer depends on context that spans the entire codebase and into the future, requiring extensive human thought.</p>

<p>In my experience, agents tend toward over-inheritance, god objects, and multi-layer hierarchies. When you tell an agent to “use OOP best practices,” what you often get back reflects the average OOP code in training data – and a lot of that code is bad.</p>

<p>The solution is exactly the same as for MVC: <strong>constrain explicitly.</strong> “Prefer composition over inheritance; maximum of one level of abstraction in the class hierarchy; no abstract factories.” Without these guardrails, agents will default to sophisticated-looking, fragile patterns.</p>

<hr />

<h2 id="c-tier-actively-fights-agent-strengths">C-Tier: Actively Fights Agent Strengths</h2>

<h3 id="mvvm">MVVM</h3>

<p>MVVM adds two issues for agents that struggle with: <strong>reactive data binding</strong> and <strong>implicit state updates</strong>. When a ViewModel’s properties change, they magically trigger an update in the view. However, which binding triggered the update? How did the order of the bindings matter? Can there be a cycle of updates from two or more bindings?</p>

<p>These bugs are ones that have no apparent presence in your code until you interact with the UI at run time to use it in some manner. A developer may write MVVM code using an agent model to create a design that appears perfect (the ViewModel is clean, all of the binding statements appear to be valid, and so on) and then discover that the application will crash due to a subtle ordering issue in how reactive event handlers subscribe.</p>

<p>The root problem is <strong>implicit control flow</strong>. The agent can’t read a ViewModel and know what will happen when a property changes without understanding every binding in every View that references that property. That’s global reasoning, and it’s where agents consistently struggle.</p>

<h3 id="event-driven-architecture">Event-Driven Architecture</h3>

<p>Similar issue to MVVM, but at a larger scope. When an application publishes an event, you don’t know how many subscribers are listening (or even what type) based solely on the event-publishing code. To debug an event-driven system you have to be aware of all subscribers in the entire system. An agent writes a publisher and subscriber independently and correctly, yet they will fail due to events arriving out of sequence, or one handler making assumptions about state that other handlers haven’t yet established.</p>

<p>The debugging required for asynchronous, event-based distributed systems is equivalent to maintaining the entire event topology in memory; this is the exact opposite of the global understanding of complex logic that degrades as software becomes more complex, as developers move outside their immediate context.</p>

<p>Of course, if an agent has already built or is working on specific event handlers for existing systems – these are examples of using local reasoning about a bounded set of code. However, the greatest risk exists during initial design of a new event-driven system where an agent must create both the event topology and determine the appropriate ordering guarantees for those events concurrently.</p>

<hr />

<h2 id="d-tier-fundamentally-misaligned-with-zero-shot-agentic-coding">D-Tier: Fundamentally Misaligned With Zero-Shot Agentic Coding</h2>

<h3 id="ddd">DDD</h3>

<p>DDD is as much a <strong>collaborative domain-modeling process</strong> as it is a set of code-level patterns. The entire point is building a “ubiquitous language” between developers and domain experts through iterative conversation – event storming, bounded context mapping, aggregate root identification. These are inherently human activities that require deep domain knowledge and extended collaboration.</p>

<p>An AI agent has no domain expert to talk to. It doesn’t understand that “Account” means something different in the billing bounded context vs. the user identity bounded context. Without deep domain knowledge fed in through exhaustive prompting, agents applying DDD tend to produce superficial models – aggregates and value objects with the right naming conventions but wrong boundaries. That can be more harmful than no DDD at all, because it creates a false sense of rigor. The code looks like it was designed by someone who understood the domain.</p>

<p>If you have the domain knowledge and can feed it into the agent through a detailed spec – essentially doing the DDD work yourself and handing the agent the conclusions – it can implement the tactical patterns fine. But at that point, you’ve done the hard part. The agent’s work is purely mechanical.</p>

<p>The ceremony cost is brutal too. A full DDD implementation produces an enormous amount of boilerplate relative to actual business logic. Every line of boilerplate is a line eating context window and a line where the agent can introduce subtle structural errors.</p>

<h3 id="microservices">Microservices</h3>

<p>Starting with microservices is often a poor default even for human teams, and it’s particularly costly for agents.</p>

<p>When you tell an agent to build a microservices architecture from scratch, here’s what it produces: multiple separate services, each needing their own deployment configuration, a service discovery mechanism, inter-service communication (HTTP? gRPC? message queues? – the agent will pick one and maybe mix in another), distributed tracing, eventual consistency handling, and an infrastructure layer that dwarfs the actual business logic.</p>

<p>The agent has no way to assess whether that complexity is warranted. The agent follows your instructions and creates exactly what you told it to create. As a result, you will be creating a system in which an error in any individual service can require information from each of all of the remaining services – and the amount of that information will exceed the size of a single agent session. In other words, debugging the system will become an archaeological process that involves multiple sessions, during which time there is nothing about what each of the other services does that is remembered by the agent.</p>

<p>Independent development and deployment (scaling) are the underlying principles of microservices. These principles are intended to allow development teams to work independently and at their own pace; they also provide fault isolation and enable teams to deploy new versions of applications independently of each other. Your new application has zero users; therefore none of these principles have been proven or demonstrated. Therefore, you are experiencing the full overhead of distributed systems on day one of operation – and you may never realize the potential benefits of using microservices.</p>

<hr />

<p>These scores are heuristic judgments based on the four axes, not empirical benchmark results.</p>

<table>
  <thead>
    <tr>
      <th>Paradigm</th>
      <th>Local Reasoning</th>
      <th>Mechanical Verification</th>
      <th>Explicit Flow</th>
      <th>Signal Ratio</th>
      <th>Grade</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>TDD</td>
      <td>★★★★★</td>
      <td>★★★★★</td>
      <td>★★★★★</td>
      <td>★★★★★</td>
      <td><strong>S</strong></td>
    </tr>
    <tr>
      <td>Functional Programming</td>
      <td>★★★★★</td>
      <td>★★★★☆</td>
      <td>★★★★★</td>
      <td>★★★★★</td>
      <td><strong>S</strong></td>
    </tr>
    <tr>
      <td>BDD</td>
      <td>★★★★★</td>
      <td>★★★★★</td>
      <td>★★★★☆</td>
      <td>★★★★☆</td>
      <td><strong>S</strong></td>
    </tr>
    <tr>
      <td>Hexagonal / Ports</td>
      <td>★★★★★</td>
      <td>★★★★☆</td>
      <td>★★★★★</td>
      <td>★★★☆☆</td>
      <td><strong>A</strong></td>
    </tr>
    <tr>
      <td>MVC</td>
      <td>★★★★☆</td>
      <td>★★★☆☆</td>
      <td>★★★★★</td>
      <td>★★★★☆</td>
      <td><strong>A</strong></td>
    </tr>
    <tr>
      <td>CQRS</td>
      <td>★★★★☆</td>
      <td>★★★★☆</td>
      <td>★★★★☆</td>
      <td>★★☆☆☆</td>
      <td><strong>B</strong></td>
    </tr>
    <tr>
      <td>OOP</td>
      <td>★★★☆☆</td>
      <td>★★☆☆☆</td>
      <td>★★★★☆</td>
      <td>★★★☆☆</td>
      <td><strong>B</strong></td>
    </tr>
    <tr>
      <td>MVVM</td>
      <td>★★☆☆☆</td>
      <td>★★☆☆☆</td>
      <td>★★☆☆☆</td>
      <td>★★★☆☆</td>
      <td><strong>C</strong></td>
    </tr>
    <tr>
      <td>Event-Driven</td>
      <td>★★☆☆☆</td>
      <td>★★☆☆☆</td>
      <td>★☆☆☆☆</td>
      <td>★★★☆☆</td>
      <td><strong>C</strong></td>
    </tr>
    <tr>
      <td>DDD</td>
      <td>★★★☆☆</td>
      <td>★★☆☆☆</td>
      <td>★★★☆☆</td>
      <td>★☆☆☆☆</td>
      <td><strong>D</strong></td>
    </tr>
    <tr>
      <td>Microservices</td>
      <td>★☆☆☆☆</td>
      <td>★★★☆☆</td>
      <td>★★☆☆☆</td>
      <td>★☆☆☆☆</td>
      <td><strong>D</strong></td>
    </tr>
  </tbody>
</table>

<hr />

<h2 id="the-ideal-agentic-stack">The Ideal Agentic Stack</h2>

<p>If I had a project today that was going to rely mostly on coding agents:</p>

<p><strong>Core functional programming with TDD.</strong> Pure functions for domain logic and exhaustively tested. Each business rule is a function (with input parameters, output values) that can be written by the agent continuously with no problems in terms of testing.</p>

<p><strong>Behavior-driven development (BDD)</strong> spec definitions at the periphery. Business-facing user behaviors are defined as Gherkin-based specifications before the agent writes specific implementation code. This helps reduce ambiguity of requirements and provides a clear objective target for the agent to implement from.</p>

<p><strong>A hexagonal architecture for structural design.</strong> Logic is located in the center of the hexagon; ports define interface boundaries; adapters connect external integration implementations to those interfaces. The agent can continue to work with an individual adapter at a time and does not need to understand how other adapters interact.</p>

<p><strong>MVC or simple request/response for edge layers.</strong> For HTTP layers and all related wiring patterns – use what the agent sees ten million times. Do not get creative here!</p>

<p><strong>Monolithic deployment.</strong> A single repository, a single deployable package, a single environment/context that the agent understands. Deploy services later when data and need exist.</p>

<p>This configuration achieves the benefits of each layer while avoiding its drawbacks: best possible local reasoning, mechanical verification at every step, most explicit control flow, least amount of ceremony.</p>

<hr />

<h2 id="the-takeaway">The Takeaway</h2>

<p>The pattern here isn’t complicated: paradigms that maximize <strong>local reasoning</strong> and <strong>mechanical verifiability</strong> tend to be agent-friendly; paradigms that require global context, design taste, or domain expertise tend to be agent-hostile.</p>

<p>While I am not opposed to Domain Driven Design (DDD), Event-Driven Architecture (EDA), and/or microservices as a whole – these are all good patterns employed by experienced teams working with large and complex systems – the reason they’re effective is that skilled people provide the necessary design judgment, domain knowledge, and global context required to support their use. At present, agents cannot provide those skills reliably. If you ask an agent to follow a paradigm based upon assumptions that it has those skills (judgment, knowledge, and so on), then you’ll be setting both your agent and yourself up for debugging.</p>

<p>You will also see that nothing above eliminates the necessity for human review. While architecture can limit the ways in which an agent fails – thus making errors less frequent and easier to identify – it cannot replace the thoroughness associated with reviews, observability, and validation. The best possible agent-friendly architecture in the world still requires a human to review its output before shipping.</p>

<p>An important aspect of the “agent-coding revolution” is that it is not about how much smarter the model becomes (it will become smarter), but rather about how software developers learn to decide which architectures enhance an agent’s capability and which create conflict. Optimize your architecture for the areas where an agent excels – i.e., local reasoning, mechanical verification, explicit control flow – and allow the agent to perform the tasks it performs best – i.e., generate vast amounts of correct code quickly while you remain focused on the decisions that truly require a human.</p>

<p>Ultimately, this is a significant shift in how one views themselves as a developer – and not merely “how do I better prompt my models?” – but instead “How do I structure my projects so that I’m minimizing opportunities for the agent to mess up?”</p>]]></content><author><name>efpasia</name></author><category term="thoughts" /><summary type="html"><![CDATA[Most of the debate around agentic coding is about tooling – which IDE, which model, which CLI to use, and so on. Much less attention goes to a more interesting question: does the way we’ve been taught to structure code even make sense when the thing writing it has limited long-term memory, a finite context window, and often has to make progress without holding the whole system in view?]]></summary></entry><entry><title type="html">How Garmin Engineered Multi-Week Battery Life Into a Watch</title><link href="https://efp.asia/blog/2026/02/22/garmin-glass/" rel="alternate" type="text/html" title="How Garmin Engineered Multi-Week Battery Life Into a Watch" /><published>2026-02-22T15:00:00+00:00</published><updated>2026-02-22T15:00:00+00:00</updated><id>https://efp.asia/blog/2026/02/22/garmin-glass</id><content type="html" xml:base="https://efp.asia/blog/2026/02/22/garmin-glass/"><![CDATA[<p>The smartwatch market is a showcase of contrasts. Most smartwatches last a day or two between charges, but with Garmin, some models display an infinity symbol where the battery percentage should be. An actual infinity symbol, meaning the watch is really gaining energy faster than it’s spending it.</p>

<p>That kind of gap comes from a stack of engineering decisions that compound on each other: the glass, the solar layer beneath it, the display technology, the choice of MCU, the firmware’s power management – all of it working together in a package that weighs ~60 grams.</p>

<p>This post unpacks two pillars of how Garmin keeps winning the battery war: <strong>the glass</strong> (how energy gets in) and <strong>the power architecture</strong> (how little energy gets used). It’s not a product review, and it’s not the usual rehash of spec sheets that you’re probably tired of reading. Think of it more as an engineering analysis – built on teardown findings, component datasheets, patent filings, and field test data.</p>

<p>We’ll trace the solar tech from its first appearance in 2019 through the current generation, crack open the watch to see what silicon is actually running the show, and look at where this technology is headed – and whether anyone else can catch up. If, like me, you have ever wondered what really goes on under that “sapphire glass”, then this post is for you.</p>

<p><img src="/assets/images/garmin-infinite-battery.webp" alt="Garmin Infinite Battery icon" /></p>

<hr />

<h2 id="from-fenix-6-to-instinct-3">From Fenix 6 to Instinct 3</h2>

<p>The story begins with an acquisition. In the years leading up to 2019, Garmin quietly acquired SunPartner Technologies, a French company specializing in transparent photovoltaic surfaces, as it was nearing bankruptcy. The goal was direct: integrate solar energy capture directly into a watch face without impairing the display. The result shipped in the Fenix 6 series – the first Garmin watch with solar charging.</p>

<p>The first design was clever but came with visible tradeoffs. A single semitransparent solar layer was bonded between the display and the cover glass, essentially creating a photovoltaic sandwich. This layer used a two-density approach: highly efficient solar cells around the display edge captured energy at near-100% photovoltaic efficiency, while a much less efficient array – roughly 10% covered the main screen area. The logic was sound: maximize harvesting at the perimeter where it doesn’t interfere with readability, and capture what you can from the rest without blocking the display entirely.</p>

<p>The solar charging feature did its job, but you couldn’t miss its presence. The layer beneath the screen gave the display a subtle reddish tint, especially noticeable if you caught it in the right light. It didn’t ruin the experience, but it was a visible sign that Garmin was still polishing up a brand-new technology.</p>

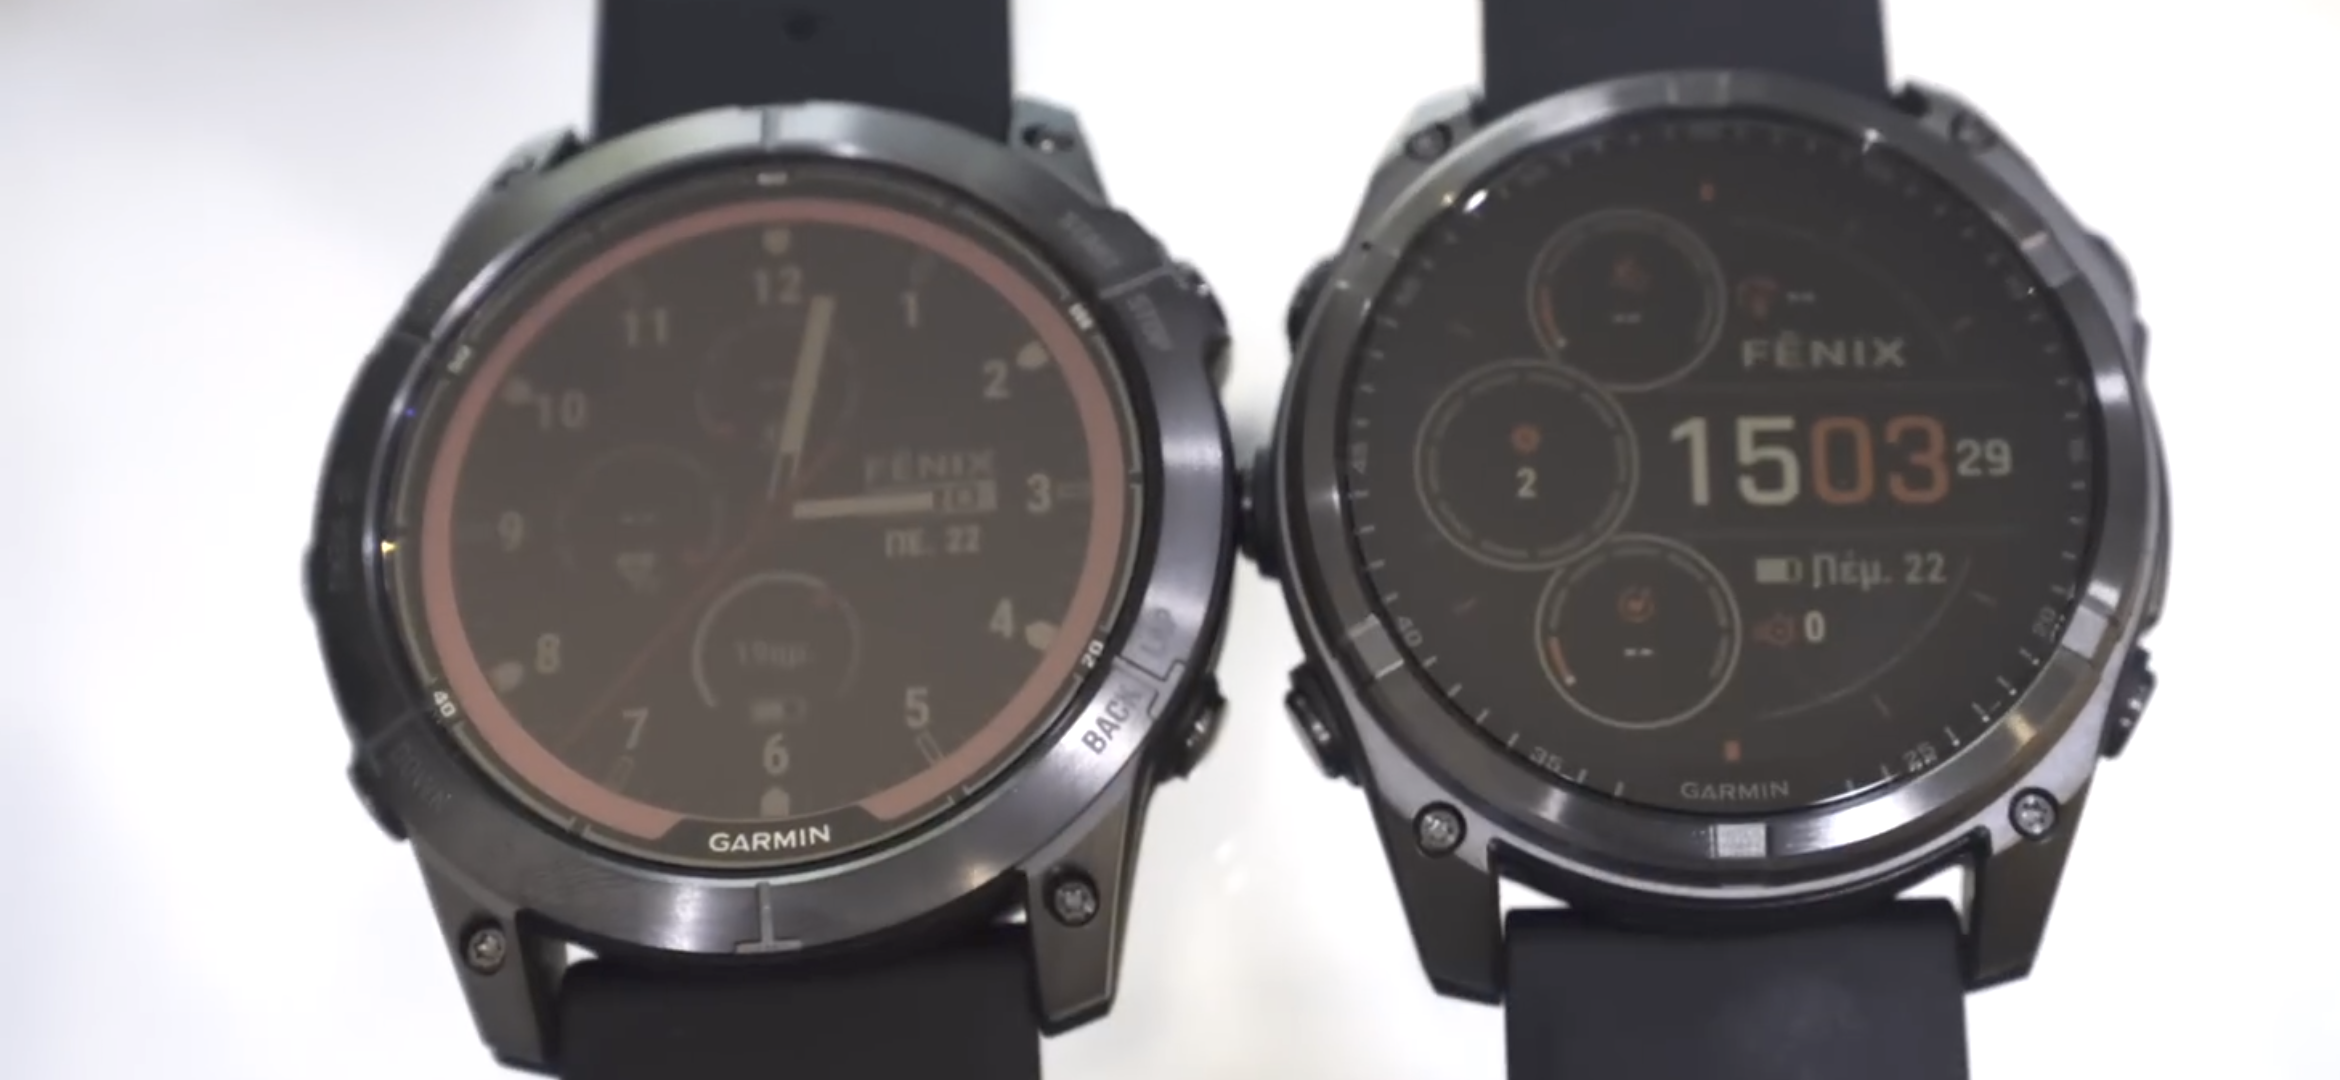
<!-- ![Garmin fenix 7 Pro Saphire Solar (2023) vs Garmin Fenix 8 Saphire Solar](/assets/images/garmin-fenix-7_vs_garmin-fenix-8.webp) -->

<figure>
  <img src="/assets/images/garmin-fenix-7_vs_garmin-fenix-8.webp" alt="Garmin fenix 7 Pro Saphire Solar (2023) vs Garmin Fenix 8 Saphire Solar" />
  <figcaption>Garmin fenix 7 Pro Saphire Solar (2023) vs Garmin Fenix 8 Saphire Solar</figcaption>
</figure>

<p><strong>From 2019 through 2024, Garmin iterated</strong>. Solar started popping up everywhere in Garmin’s lineup – first in the Instinct Solar, then the Instinct 2 Solar, the Enduro series for endurance diehards, and even on Edge bike computers. Each release brought solar tech to a new crowd at a different price, but under the hood, the tech didn’t change: same dual-density solar panels, same hidden layer between glass and display, and that reddish hue.</p>

<p>That changed in late 2024 with the Fenix 8 Solar and Enduro 3.</p>

<p>These were the first Garmin watches to ship a meaningfully redesigned solar architecture since the earliest Fenix 6. The changes were structural, not incremental. Garmin relocated the solar component entirely off the main screen area – instead of a semitransparent layer sitting over the display pixels, the solar cells now lived exclusively on the non-screen bezel portions of the watch face, packed at a much higher density. The red tint was gone. Paired with a Power Sapphire lens – sapphire crystal, the second-hardest transparent material after diamond – the Enduro 3 pushed the marketed battery life to 90 days with solar in smartwatch mode and 320 hours of GPS tracking.</p>

<p><a href="https://ph.garmin.com/news/press-release/news-2020-aug-solar/">Garmin claimed up to 5× the solar charging power of the previous generation</a>, and actual data confirmed it. The architecture delivered those gains where they mattered most: sustained GPS tracking for people who actually need multi-day battery life in the field.</p>

<p>In January 2025, this Gen 2 solar technology trickled down from the premium tier into the Instinct 3 Solar – the first meaningful solar hardware upgrade for that series. Garmin paired the new solar architecture with a redesigned MIP display, and the results were awesome. Where the Instinct 2 Solar managed 48 hours of GPS-only tracking with solar, the Instinct 3 Solar <a href="https://www8.garmin.com/manuals/webhelp/GUID-31D23DBB-57C2-4DF7-A0C9-8D1A00AB4BE7/EN-US/GUID-BCA44331-7CAC-4734-9222-6066B05C32AB.html">pushed that to 130 hours</a>. In Max Battery GPS mode, it achieved what Garmin officially labels “unlimited” battery life with adequate sun exposure – and independent reviewers confirmed it, logging burn rates under 1% per hour in high-drain GPS modes. A watch that costs a fraction of the Fenix 8 Solar, running the same solar tech, hitting “unlimited” in multiple modes. That’s when you know a generation jump is real</p>

<table>
  <thead>
    <tr>
      <th>Year</th>
      <th>Product</th>
      <th>Solar Gen</th>
      <th>What Changed</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>2019</td>
      <td>Fenix 6 Solar</td>
      <td>Gen 1</td>
      <td>First solar Garmin – dual-density panel, reddish tint</td>
    </tr>
    <tr>
      <td>2020</td>
      <td>Instinct Solar</td>
      <td>Gen 1</td>
      <td>Solar enters the mid-tier lineup</td>
    </tr>
    <tr>
      <td>2022</td>
      <td>Instinct 2 Solar</td>
      <td>Gen 1</td>
      <td>Broader availability, same core architecture</td>
    </tr>
    <tr>
      <td>2024</td>
      <td>Fenix 8 Solar / Enduro 3</td>
      <td>Gen 2</td>
      <td>Bezel-only cells, no tint, Power Sapphire, 5× power</td>
    </tr>
    <tr>
      <td>2025</td>
      <td>Instinct 3 Solar</td>
      <td>Gen 2</td>
      <td>Gen 2 solar trickles down, “unlimited” in multiple modes</td>
    </tr>
  </tbody>
</table>

<h2 id="whats-actually-under-the-glass">What’s actually under the glass?</h2>

<p>Every Garmin solar watch is, at its core, a sandwich – a literal stack of layers, each with a specific job, bonded together in a precise order. Understanding this stack is the key to understanding why these watches behave the way they do in the real world.</p>

<h3 id="the-solar-sandwich">The Solar Sandwich</h3>

<p>The structure, from the outside in, goes: cover lens → solar charging layer → display → motherboard. That’s it. The solar component doesn’t sit on top of the watch or clip on as an accessory – it’s embedded between the glass you touch and the pixels you read. This is why you can’t tell most Garmin solar watches have solar capability just by looking at them.</p>

<p>Where things get interesting is the cover lens itself. Garmin offers two variants:</p>

<p><strong>Power Glass</strong> uses a standard strengthened glass lens with solar cells bonded to its underside. It’s durable, optically clear, and shows up on mid-tier products like the Instinct series. It does the job well, but glass is glass – it scratches.</p>

<p><strong>Power Sapphire</strong> replaces that glass with synthetic sapphire crystal. Sapphire is the second-hardest transparent material after diamond, rating 9 on the Mohs scale. That means it’s essentially unscratchable in normal use. The solar component sits under this sapphire layer, fully protected. Power Sapphire shows up on the Fenix 8 Solar, Enduro 3, and tactix 8 Solar – the watches Garmin expects to get really field tested.</p>

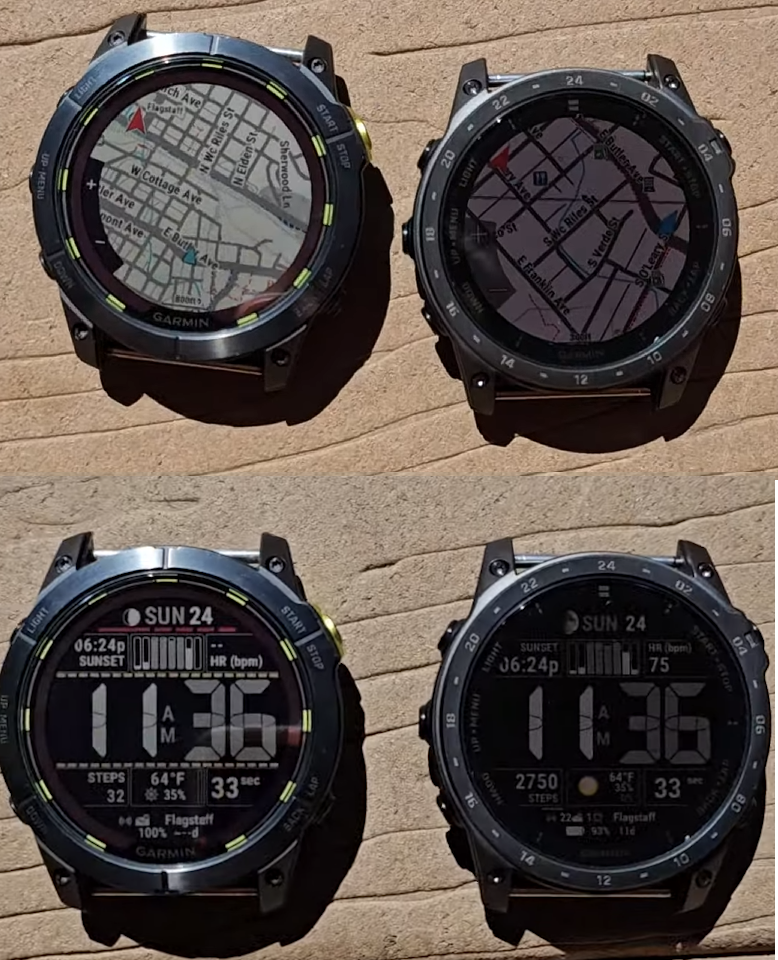
<p>In the Gen 1 design (2019–2024), the solar panel was semitransparent and stretched across the entire watch face – both the bezel area and the main display. In the Gen 2 design (2024+), the solar cells moved entirely to the non-screen portions of the face, sitting in a dense ring around the display. This is why Gen 2 eliminated the reddish tint: there’s simply no solar material between your eyes and the pixels anymore.</p>

<!-- ![Gen 1 (2019–2024) on the left and Gen 2 (2024+) on the right comparison](/assets/images/garmin-glass.png) -->

<figure>
  <a href="/assets/images/garmin-glass.png" target="_blank">
    <img src="/assets/images/garmin-glass.png" alt="Gen 1 (2019–2024) on the left and Gen 2 (2024+) on the right comparison" />
  </a>
  <figcaption>
    Gen 1 (2019–2024) on the left and Gen 2 (2024+) on the right comparison
  </figcaption>
</figure>

<h3 id="photovoltaic-efficiency-and-panel-orientation">Photovoltaic Efficiency and Panel Orientation</h3>

<p>Not all parts of the solar layer are pulling their weight. In the Gen 1 setup, only the thin ring of solar cells around the edge of the display worked at close to full efficiency. Most of the main screen was covered by a semitransparent solar array that let about 90% of light pass through so you could actually see the watch face. That means only about 10% of the incoming light was even available for solar conversion. And when you factor in the limitations of the thin film tech, the actual energy conversion rate for the center of the screen drops below 1%, while perimeter cells do most of the charging with ~8-10% net effective efficiency.</p>

<p>But raw cell efficiency is only half the equation. The other half is geometry.</p>

<p>Solar panels are at their best when sunlight hits them straight on, at a perfect 90-degree angle to the surface. As soon as you tilt the panel, the output starts to fall off – sometimes fast. With a curved watch face, you’re already taking about a 20% hit compared to a flat panel, just because the light isn’t hitting every part evenly. That’s the easy part. The bigger challenge is how often a wearable is angled away from the sun. If the panel is facing sideways (90 degrees off from the sun), output doesn’t just dip – <a href="https://the5krunner.com/2025/11/27/garmin-solar-technology-power-glass-unlimited-battery-mip/">it drops to about one-sixth of what you’d get at the optimal angle</a>. And the reality is, your wrist is rarely pointed directly at the sun. Whether you’re running, hiking, or just walking around, the angle of your watch keeps shifting, which means the amount of sunlight hitting the panel is all over the place from moment to moment.</p>

<p>Garmin’s engineers know this, so they don’t just rely on a single orientation for their solar panels. Instead, the solar array is made up of multiple tiny panels, each set at a slightly different angle. The idea isn’t to chase the perfect sunbeam all day, but to make sure the watch grabs at least some energy no matter how you move. That way, whether you’re checking your pace, grabbing a snack, or waving at a friend, your watch keeps soaking up what it can.</p>

<p>The entire array is managed by a Power Management Unit running <strong>Maximum Power Point Tracking (MPPT)</strong> algorithms. MPPT is a technique borrowed from rooftop and industrial solar installations: the controller continuously adjusts the electrical operating point of the solar cells to extract the maximum possible power at any given moment, accounting for changing light intensity, angle, and temperature. It’s the same principle your home solar inverter uses.</p>

<p>Garmin’s stated benchmark is <a href="https://garminkw.com/product/instinct-2x-solar-graphite/">3 hours per day at 50,000 lux</a> – that’s bright outdoor sunlight, roughly what you’d get on a clear day at mid-latitudes. For reference, full direct sun near the equator at altitude can hit 150,000 lux – 2x-3x the benchmark.</p>

<h3 id="the-real-numbers">The Real Numbers</h3>

<p>Under favorable conditions–when the watch is left unused in direct sunlight throughout the day–Garmin solar technology can restore <a href="https://the5krunner.com/2025/11/27/garmin-solar-technology-power-glass-unlimited-battery-mip/">approximately 20% of the battery charge</a>. This is when using early Gen 1 equipment; Gen 2 improves this figure. However, the charging rate follows a diminishing-returns curve. As the battery charges, the rate at which it charges from solar energy decreases. Charging from 10% to 30% is noticeably faster than charging from 80% to 100%. This is standard lithium-ion charging behavior, but it means solar is most impactful when you need it most – when the battery is low.</p>

<p>For cycling products like the Edge 840 Solar and Edge 1040 Solar, Garmin quantifies solar contribution differently: as “ride gain.” Roughly 20 extra minutes of battery life for every hour of riding in the sun. Whether Garmin expands this kind of solar quantification to future watch models still to be seen, but it’s a smart way to make an invisible feature feel concrete.</p>

<hr />

<h2 id="inside-the-watch--what-the-teardowns-reveal">Inside the Watch – What the Teardowns Reveal</h2>

<p>Spec sheets tell you what a watch does. Teardowns tell you how – and sometimes why. Cracking open three generations of Garmin hardware reveals a story of platform evolution, strategic component reuse, and some surprising decisions about what changes between price tiers and what doesn’t.</p>

<h3 id="the-brain-from-cortex-m4-to-cortex-m33">The Brain: From Cortex-M4 to Cortex-M33</h3>

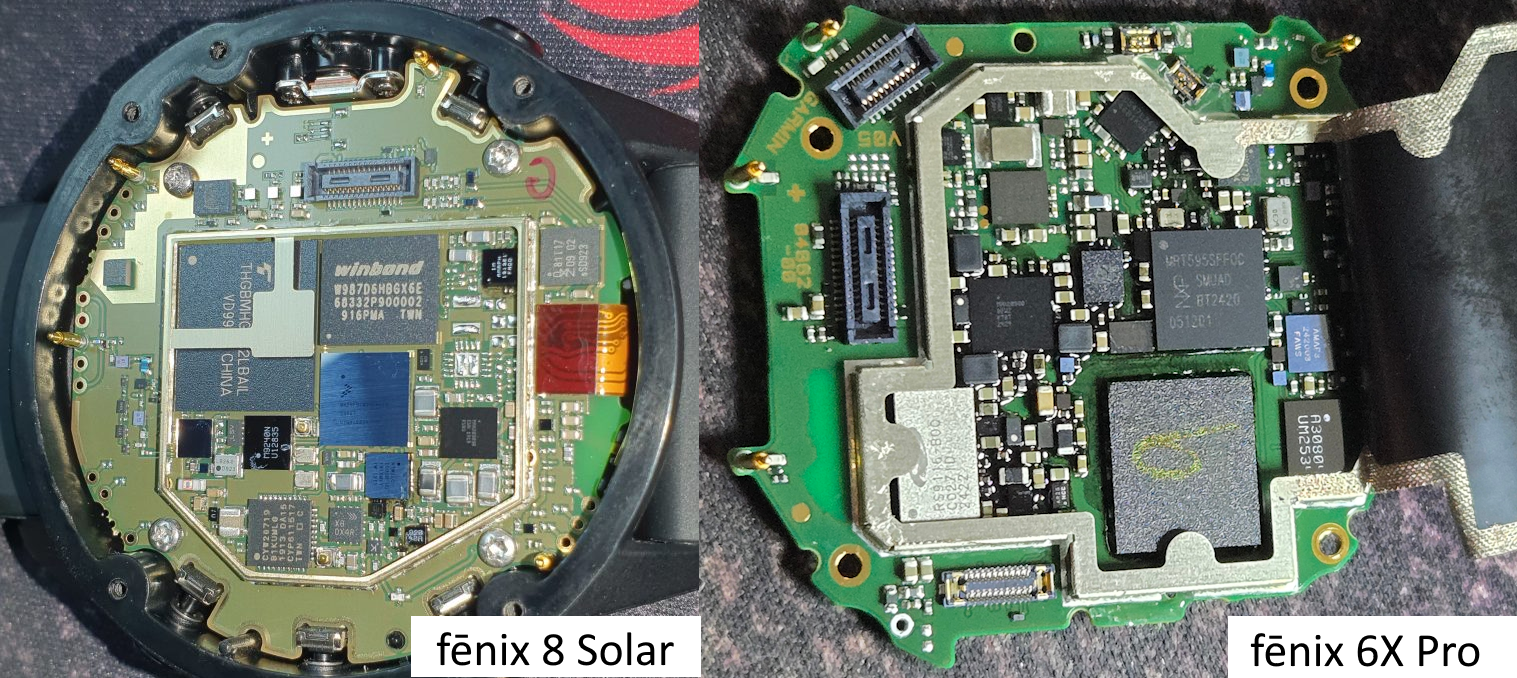
<p>The Fenix 6X Pro (2019) ran on an <a href="https://www8.garmin.com/manuals/webhelp/fenix66s6xpro/EN-GB/GUID-9DF0C26B-D40D-4CE9-801C-B8E6E1860F49.html">NXP Kinetis MK28FN2M0</a> – a 150 MHz ARM Cortex-M4 with a single-precision floating point unit, 2 MB of flash, and 1 MB of SRAM. Garmin’s firmware ran directly on the metal – no Android, no heavyweight OS – and the Cortex-M4’s job was to be efficient, not fast. The 150 MHz top speed was a burst mode (NXP calls it HSRUN), used sparingly the way Intel uses Turbo Boost: hit peak clock for a brief computation, then drop back down. Normal operation likely sat well below that ceiling, with Garmin’s firmware aggressively managing clock scaling to keep power draw minimal.</p>

<p>This same chip powered the Fenix 5 Plus series before it. Garmin got multiple product generations out of a single processor – a pattern that continues to this day.</p>

<p>Fast forward to the Fenix 8 (late 2024), and the brain has finally changed. The main SoC is now an <a href="https://www.nxp.com/products/i.MX-RT500">NXP i.MX RT500</a> (MRT595SFF0C) – a dual-core processor pairing an ARM Cortex-M33 main core with a Cadence Xtensa Fusion F1 DSP, both capable of running up to 200 MHz. The Cortex-M33 is a generational step up from the M4: it adds TrustZone security extensions, improved branch prediction, and better power efficiency at equivalent workloads. The DSP core handles audio processing – relevant now that the Fenix 8 has a speaker and microphone.</p>

<p>Interestingly, the heart of this watch is the same silicon used in the Fenix 7X. While that might seem like a carry-over, it’s actually a standard in the industry. These ultra-efficient Cortex-M chips don’t follow the yearly upgrade cycle of a smartphone; instead, they focus on maximizing every drop of power. There truly isn’t a better-suited chip on the market for this mix of performance and efficiency. The RT500 remains highly capable, <a href="https://www.zlgmcu.com/data/upload/file/Utilitymcu/IMXRT500EC.pdf">featuring 5 MB of on-board SRAM and a 2D graphics engine</a>. Its most impressive trick is granular power management – effectively shutting down unused memory blocks to save energy. It’s this level of optimization that allows for weeks of battery life rather than days.</p>

<p>Moving to 5 MB of on-chip SRAM marks a significant departure from the Fenix 6X Pro’s design. Older generations required external <strong>W987D6HB</strong> LPDDR RAM – like the 16 MB Winbond chip found in the 6X –primarily to buffer map data. With the Fenix 7 and 8, Garmin has eliminated that external chip entirely. Using the RT500’s internal memory instead removes a major power-drain and reduces latency, even if it means map rendering is visibly slower than on devices with external RAM. It’s a classic Garmin optimization: they’ve intentionally traded UI “snappiness” for the extreme battery endurance the series is known for.</p>

<h3 id="the-generational-comparison">The Generational Comparison</h3>

<table>
  <thead>
    <tr>
      <th>Component</th>
      <th>Fenix 6X Pro (2019)</th>
      <th>Fenix 8 Solar 51mm (2024)</th>
      <th>What Changed</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Main SoC</td>
      <td>NXP Kinetis K28F (Cortex-M4, 150 MHz)</td>
      <td>NXP i.MX RT500 (Cortex-M33 + DSP, 200 MHz)</td>
      <td>Architecture upgrade, integrated DSP and GPU</td>
    </tr>
    <tr>
      <td>RAM</td>
      <td>16 MB external LPDDR (Winbond)</td>
      <td>5 MB on-chip SRAM (no external)</td>
      <td>Eliminated external chip; less total, more efficient</td>
    </tr>
    <tr>
      <td>Storage</td>
      <td>32 GB eMMC (Toshiba)</td>
      <td>32 GB eMMC (Foresee)</td>
      <td>Same capacity, different vendor</td>
    </tr>
    <tr>
      <td>GNSS</td>
      <td>Sony CXD5603GF (single-band, 6 mW)</td>
      <td>Synaptics SYN4778 (multi-band, 7nm)</td>
      <td>Major upgrade – dual-frequency, more constellations</td>
    </tr>
    <tr>
      <td>BT/WiFi</td>
      <td>Cypress CYW20719 + Atmel ATWILC 1000B (separate)</td>
      <td>Silicon Labs RS9116-B00 (combined)</td>
      <td>Consolidated into single chip</td>
    </tr>
    <tr>
      <td>PMIC</td>
      <td>Maxim MAX20303B</td>
      <td>Maxim MAX20360</td>
      <td>Updated, same lineage</td>
    </tr>
    <tr>
      <td>Sensor Hub</td>
      <td>Ambiq Apollo 2 (Cortex-M4, 48 MHz)</td>
      <td>Ambiq Apollo 3 (Cortex-M4F, 48–96 MHz)</td>
      <td>Incremental upgrade</td>
    </tr>
    <tr>
      <td>Audio</td>
      <td>None</td>
      <td>Cirrus Logic CS47L24 codec + MEMS mic + speaker</td>
      <td>Entirely new subsystem</td>
    </tr>
    <tr>
      <td>Touch</td>
      <td>None (buttons only)</td>
      <td>Cypress/Infineon PSoC 4000S (Cortex-M0+)</td>
      <td>New dedicated touch controller</td>
    </tr>
    <tr>
      <td>NFC</td>
      <td>NXP PN81T</td>
      <td>NXP 22T3XR</td>
      <td>Updated, same function</td>
    </tr>
    <tr>
      <td>Battery</td>
      <td>420 mAh, 3.8V, 1.596 Wh</td>
      <td>618 mAh, 3.91V, 2.42 Wh</td>
      <td>47% more capacity</td>
    </tr>
  </tbody>
</table>

<p>While the 32 GB storage and Maxim PMIC remain unchanged, Garmin didn’t just sit on their hands. By moving the RAM directly onto the SoC and consolidating the wireless chips, they simplified the watch’s “brain” to save the energy. The standout upgrade is the new 7nm Synaptics GNSS chip: switching from an older Sony single-band solution to a modern, multi-constellation, dual-frequency chip is arguably the most significant functional improvement we’ve seen between these two models.</p>

<h3 id="the-dirty-secret-same-silicon-across-price-tiers">The Dirty Secret: Same Silicon Across Price Tiers</h3>

<p>Now here’s where it gets interesting for anyone shopping between a $350 Forerunner and a $1,000+ Fenix.</p>

<p>A teardown of the <strong>Forerunner 245 Music</strong> (a mid-tier watch from 2019, the same generation as the Fenix 6X Pro) revealed that the major internal components – including the ARM processors – were <strong>99% identical</strong> to the Fenix series. Same NXP Kinetis main CPU. Same core architecture. The differences came down to peripheral additions: NFC presence, sensor count, storage capacity, and crucially, software-enabled features (that’s the key selling point)</p>

<p>This means the platform-level efficiency gains – clock scaling, power management firmware, GNSS optimizations flow across the entire lineup. When Garmin’s firmware team improves power management on the Fenix, those improvements benefit the Forerunner too, since they run on the same silicon.</p>

<p>There are two ways to read this. On one side: Garmin gates features in software to justify higher price tiers on effectively identical hardware. On the other hand, a shared development platform means cheaper watches get the same stability, bug fixes, and productivity improvements as the flagships – rather than being left on an orphaned codebase. Both readings are probably true simultaneously. But from a battery-power-efficiency standpoint, the implication is clear: the engineering investment Garmin makes at the top of the lineup compounds downward through the product line.</p>

<h3 id="the-battery-itself">The Battery Itself</h3>

<p>The Fenix 6X Pro packed <a href="https://www8.garmin.com/manuals/webhelp/fenix66s6xpro/EN-GB/GUID-9DF0C26B-D40D-4CE9-801C-B8E6E1860F49.html">a 420 mAh, 3.8V lithium-ion cell</a> (1.596 Wh) manufactured by Routejade Inc. – actually 10 mAh less than the Fenix 5X before it, yet lasting significantly longer thanks to the hardware and firmware optimizations described above.</p>

<p>The Fenix 8 51mm jumps <a href="https://www8.garmin.com/manuals/webhelp/GUID-EECCAC99-90D6-4AB1-9A3A-EC433D3365E2/EN-US/fenix_8_Series_OM_EN-US.pdf">to 618 mAh at 3.91V</a> (2.42 Wh) – a 47% increase in raw capacity. Combined with the more efficient SoC, consolidated radio chips, and improved GNSS, this is how you get from the Fenix 6X Pro’s 21-day smartwatch claim to the Fenix 8 Solar’s 48-day-with-solar claim.</p>

<p>One detail from the Fenix 6X Pro teardown worth noting: there was an <strong>empty chip space</strong> on the motherboard near the PMIC, positioned exactly where a solar charge management IC would sit. The non-solar Fenix 6X Pro was literally designed with a space for the solar variant’s hardware.</p>

<p><img src="/assets/images/teardown.png" alt="Fenix 8 Solar &amp; Fenix 6X Pro teardown" /></p>

<hr />

<h2 id="mip-vs-amoled--the-display-tradeoff-at-the-heart-of-battery-life">MIP vs. AMOLED – The Display Tradeoff at the Heart of Battery Life</h2>

<p>If you’ve made it this far into the internals, you’ve seen how Garmin squeezes efficiency out of every chip on the motherboard. But none of it matters as much as one decision that’s visible every time you glance at your wrist: which display technology is behind the glass.</p>

<p>Garmin offers two types across its lineup, and the choice between them determines how long the watch lasts, how well solar charging works, and ultimately who the watch is built for.</p>

<h3 id="mip-the-efficiency-play">MIP: The Efficiency Play</h3>

<p>Memory-in-Pixel (MIP) displays are transflective – they reflect ambient light back through the display to create a visible image. In direct sunlight, an MIP panel actually gets easier to read. No backlight is needed during the day, and the display draws power only when pixels change, not to maintain a static image. This is fundamentally different from how most screens work, and it’s why MIP watches can idle for weeks.</p>

<p>The tradeoff is real: MIP panels look dated next to modern AMOLED screens. Lower contrast, muted colors, no deep blacks. The Enduro 3’s MIP display is noticeably improved over the Enduro 2 – brighter, better viewing angles, and the solar ring is no longer a visible red bar at the perimeter – but put it next to a Fenix 8 AMOLED and the gap is obvious. Garmin is not unaware of this. They’re deliberately choosing it, and the battery numbers explain why.</p>

<h3 id="amoled-the-experience-play">AMOLED: The Experience Play</h3>

<p>AMOLED panels are beautiful. Each pixel emits its own light – vivid colors, true blacks, sharp text, smooth animations. Garmin offers AMOLED variants across the Fenix 8, Instinct 3, and Venu lines, and they look like a completely different product category from their MIP siblings. But every one of those self-lit pixels draws power, constantly, for as long as the display is on.</p>

<table>
  <thead>
    <tr>
      <th>Model</th>
      <th>Display</th>
      <th>Smartwatch Battery</th>
      <th>GPS Battery</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Fenix 8 51mm AMOLED</td>
      <td>AMOLED</td>
      <td>Up to 29 days</td>
      <td>Up to 84 hrs</td>
    </tr>
    <tr>
      <td>Fenix 8 51mm Solar</td>
      <td>MIP + Solar</td>
      <td>30 days (48 w/ solar)</td>
      <td>149 hrs (332 w/ solar)</td>
    </tr>
    <tr>
      <td>Instinct 3 50mm AMOLED</td>
      <td>AMOLED</td>
      <td>Up to 24 days</td>
      <td>Up to 28 hrs</td>
    </tr>
    <tr>
      <td>Instinct 3 50mm Solar</td>
      <td>MIP + Solar</td>
      <td>40 days (∞ w/ solar)</td>
      <td>Unlimited w/ solar</td>
    </tr>
    <tr>
      <td>Enduro 3</td>
      <td>MIP + Solar</td>
      <td>36 days (90 w/ solar)</td>
      <td>120 hrs (320 w/ solar)</td>
    </tr>
  </tbody>
</table>

<p>Look at the Instinct 3 row. Same watch generation, same chassis, same processor, same solar-or-not decision point – but the AMOLED variant tops out at 24 days and 28 hours of GPS. The MIP Solar variant hits unlimited in multiple modes. That’s not a small delta. That’s a different product category.</p>

<h3 id="why-mip--solar-is-the-killer-combo">Why MIP + Solar Is the Killer Combo</h3>

<p>Garmin’s solar charging isn’t pumping tons of power into your watch – think tiny amounts, measured in milliwatts. But because an MIP display sips so little energy, even that trickle of solar has a meaningful dent. Low power use plus a steady solar top-up means you can actually break even – or even come out ahead. That’s how you end up with the little infinity symbol instead of a battery percentage.</p>

<p>On an AMOLED watch, the display’s power hunger dwarfs the solar contribution. The solar panel would be feeding a furnace with a candle. This is why Garmin doesn’t offer a solar AMOLED watch – and why every model that displays ∞ for battery life uses an MIP panel.</p>

<p>Garmin has filed <strong>patents for solar AMOLED technology</strong>, which suggests they’re at least exploring the problem. But the physics is stubborn: AMOLED’s power floor would need to drop by an order of magnitude, or solar efficiency would need a generational leap, before the combination makes practical sense. For now, it remains just a patent filing.</p>

<figure>
  <img src="/assets/images/MIP_vs_OLED.png" alt="MIP (left) vs. OLED (right)" />
  <figcaption>MIP (left) vs. OLED (right)</figcaption>
</figure>

<hr />

<h2 id="the-competitive-landscape-and-where-things-are-heading">The Competitive Landscape and Where Things Are Heading</h2>

<p>We’ve spent the last several sections inside Garmin’s hardware. Now let’s zoom out and ask the obvious question: is anyone else doing this, and where does the technology go from here?</p>

<h3 id="the-competition--or-lack-of-it">The Competition – or Lack of It</h3>

<p>Garmin launched its first solar watch in 2019. Six years later, the competitive response has been remarkably thin.</p>

<p>Apple sits at the opposite end of the design philosophy. The Apple Watch Ultra 3 – Apple’s most endurance-focused wearable at $800 – offers roughly 14 hours of GPS recording with full accuracy. That’s a single long day in the mountains, maybe. Most Garmins deliver two, three, or four times that without solar, and models like the Enduro 3 push past 300 hours with it. Apple optimizes for a different set of priorities – cellular connectivity, a rich app ecosystem, deep iPhone integration – but if your use case involves being away from a charger for more than 36 hours, it’s not a competitive option. The comparison isn’t even close enough to require a table.</p>

<p>Coros is the more interesting competitor. They’ve built a strong reputation for lightweight, long-battery GPS watches at aggressive price points, and they actually shipped a solar product: the <a href="https://www.wired.com/review/coros-dura-solar-gps-bike-computer/">DURA bike computer</a>. On paper, the DURA’s solar implementation rivaled or exceeded Garmin’s Edge units. In practice, the product shipped with enough software and reliability issues that it hasn’t translated into real competitive pressure – at least not yet. Critically, Coros still has no solar watch in its lineup. Their watches compete on efficiency alone, and they do it well, but they haven’t attempted the solar integration that defines Garmin’s leading products.</p>

<p>Most other wearable manufacturers – Samsung and Polar – haven’t shipped solar at all. Suunto made a brief attempt with the first-generation Suunto Vertical, which included solar charging, but interestingly removed this feature in the second generation (which switched to an AMOLED display). Garmin’s moat here isn’t just the solar lens itself. It’s the vertical integration: the Power Sapphire lens, the MIP display optimized for low power, the MPPT power management, the aggressive firmware clock scaling – all developed in-house and refined over six years and two hardware generations. Replicating any one piece is feasible. Replicating the stack is a multi-year engineering program.</p>

<h3 id="why-solar-wins--and-why-nothing-else-is-close">Why Solar Wins – and Why Nothing Else Is Close</h3>

<p>If you’re wondering whether alternative energy harvesting could eventually replace or supplement solar on wearables, the physics is blunt. Here’s what each approach produces per square centimeter:</p>

<table>
  <thead>
    <tr>
      <th>Technology</th>
      <th>Power Output</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Photovoltaic (solar)</td>
      <td>1–10 mW/cm²</td>
    </tr>
    <tr>
      <td>Triboelectric (friction)</td>
      <td>0.01–0.1 mW/cm²</td>
    </tr>
    <tr>
      <td>Piezoelectric (motion)</td>
      <td>&lt; 0.01 mW/cm²</td>
    </tr>
    <tr>
      <td>Thermoelectric (body heat)</td>
      <td>&lt; 0.001 mW/cm²</td>
    </tr>
  </tbody>
</table>

<p>On a device with a few square centimeters of harvestable surface, nothing else generates enough energy to meaningfully affect battery life. <a href="https://www.nature.com/articles/s41598-022-23735-0">Thermoelectric generators</a> – the “charge your watch from body heat” concept that surfaces periodically in tech press – produce so little power on a wrist-sized device that they can’t even offset the energy cost of reading the sensor that measures the temperature differential. Solar isn’t just the best option for wearables right now – it’s the only option that works.</p>

<h3 id="the-paradox-of-efficiency">The Paradox of Efficiency</h3>

<p>Here’s where the long-term trajectory gets interesting, and slightly contradictory.</p>

<p>Every generation of hardware is getting more efficient on its own. The jump <a href="https://garminrumors.com/garmin-fenix-8-teardown-whats-actually-new-inside/">from the Sony CXD5603GF GNSS chip (Fenix 6X) to the Synaptics SYN4778 (Fenix 8)</a> brought both multi-band capability and lower power consumption. MIP displays are getting brighter without drawing more power. Processors are consolidating functions – Bluetooth and WiFi merged into a single chip, external RAM eliminated – reducing total board power. The result: non-solar models now routinely deliver multi-week battery life that would have been flagship-tier a few years ago.</p>

<p>This creates a reasonable question: if the baseline is already this good, <strong>does solar still matter</strong>?</p>

<p>The answer is yes, but the reason flips. When overall power draw was high, solar was a modest supplement – a few extra hours here and there. Now that power draw is low, solar’s contribution represents a much larger percentage of total consumption. A few milliwatts of solar input against a watch drawing 50 milliwatts is noise. The same input against a watch drawing 5 milliwatts is transformative. This is exactly how the Instinct 3 Solar reaches “unlimited” in modes where the Instinct 2 Solar couldn’t – the Gen 2 solar hardware is better, but the lower-power platform is doing just as much of the work.</p>

<p>That said, solar doesn’t make sense everywhere. Garmin’s newer Edge bike computers use Transmissive LCD displays – large, power-hungry screens where solar gains are marginal relative to total consumption. Garmin quietly dropped the solar option for these models, which suggests the company is being rational rather than dogmatic about where solar adds genuine value.</p>

<h3 id="what-to-watch-for">What to Watch For</h3>

<p>Looking ahead, a few things have me really curious. Garmin’s work on solar AMOLED is easily the most intriguing – if they can make that work without killing the battery, it changes everything. More realistically, expect MIP screens to keep closing the gap; they’re getting so good that the outdoor legibility “advantage” over AMOLED is becoming a given. We’ll also see new GPS chipsets that sip power rather than gulping it, which is great for anyone doing long efforts. It’ll also be interesting to see if anyone else–looking at you, Coros – can actually build a solar watch that works. Garmin has a massive head start, but in tech, no lead is ever truly safe.</p>

<p>We might not know the exact timeline, but we know the direction, since every part of the watch is trending toward “ultra-low power,” and solar efficiency keeps rising. We’re already at the point where these watches can live forever in low-power modes. Now, the challenge is seeing how much of the “smart” stuff we can keep running before the battery starts to dip.</p>

<h2 id="who-actually-needs-this">Who Actually Needs This?</h2>

<p>After a ton of text on silicon, solar physics, and teardown photos, it’s worth asking the practical question: should you actually pay the solar premium?</p>

<p>If you’re planning multi-day expeditions, running ultras, bike touring across remote terrain, or simply the kind of person who forgets to charge things and resents being punished for it, solar with an MIP display is definitely a choice. You pay more upfront for the ability to stop thinking about battery life entirely. For these use cases, nothing else on the market comes close, and it’s not a competitive gap that’s closing anytime soon.</p>

<p>If you’re a daily gym-goer who charges every night on the nightstand anyway, an AMOLED Garmin – or frankly any modern smartwatch – is perfectly fine. Solar is a useful extra at that point, not a necessity. The beautiful screen will matter more to you than an extra two weeks of theoretical runway you’ll never use.</p>

<p>After all, the small infinity symbol on your wrist means that you are wearing something special. It is not just a clever invention, but the result of a whole series of engineering tricks, which you now know more about. That “∞” isn’t just a flex; it’s a reminder that every layer inside is doing its part to keep you going, no matter where you take it!</p>

<hr />

<p><em>Edited 23 Feb 2026 to correct Suunto information. Thanks to <a href="https://www.reddit.com/r/GarminWatches/comments/1rby52c/comment/o6wycd0/">this Reddit comment</a>.</em></p>]]></content><author><name>efpasia</name></author><category term="thoughts" /><summary type="html"><![CDATA[The smartwatch market is a showcase of contrasts. Most smartwatches last a day or two between charges, but with Garmin, some models display an infinity symbol where the battery percentage should be. An actual infinity symbol, meaning the watch is really gaining energy faster than it’s spending it.]]></summary></entry><entry><title type="html">The API Tooling Crisis: Why developers are abandoning Postman and its clones?</title><link href="https://efp.asia/blog/2025/12/24/api-tooling-crisis/" rel="alternate" type="text/html" title="The API Tooling Crisis: Why developers are abandoning Postman and its clones?" /><published>2025-12-24T15:00:00+00:00</published><updated>2025-12-24T15:00:00+00:00</updated><id>https://efp.asia/blog/2025/12/24/api-tooling-crisis</id><content type="html" xml:base="https://efp.asia/blog/2025/12/24/api-tooling-crisis/"><![CDATA[<p>I’ve been a Postman user for my entire developer career. I remember when it was just a simple Chrome extension that made <del>pen</del>testing APIs slightly less painful. Those were simpler times. Today, I find myself joining the growing exodus of developers abandoning these tools because they <a href="https://geohot.github.io/blog/jekyll/update/2021/04/20/sell-outs.html">sell out</a>.</p>

<h2 id="the-great-betrayal-how-our-favorite-tools-turned-against-us">The Great Betrayal: how our favorite tools turned against us</h2>

<p>There’s a disappointing pattern growing in the API tooling space that reflects what we’ve seen with other developer tools: a promising product gains support and adoption, then corporate pressures force it into enshittification.</p>

<p>Postman, once the darling of developers everywhere, has become the poster child for this transformation. The breaking point for many was the removal of the Scratchpad (offline mode). After that, degraded performance due to bloating and cloud lock-in. Suddenly, we were forced to sync our work to Postman’s cloud to access basic functionality (wasup Microsoft?). First of all, it’s spokes in wheels for the developers working on sensitive projects in banking, healthcare, or government sectors. I mean, that’s the point - to make them pay for the tool, to maximize shareholder value, and collateral damage dealt to the industry is not taken into account.</p>

<p>I tried to work around it. I attempted to use their “Lightweight API Client” which turned out to be a crippled version that barely functioned. Eventually, I gave up and started looking elsewhere.</p>

<p>Insomnia, which had positioned itself as the clean alternative to Postman, followed the same path, being architected as a copy of Postman. Version 8.0 locked users out of their local collections behind a mandatory login screen. The community backlash was <a href="https://github.com/ArchGPT/insomnium">visible and fierce</a>, but the fork was <a href="https://modernorange.io/item/41128221">abandoned</a> and probably not used by anyone, while the original product became “another one corporate asset”.</p>

<p>Thunder Client, the VS Code extension that promised simplicity, executed what can only be described as a <a href="https://medium.com/@evanwilson9463/it-s-time-to-ditch-the-thunder-client-vscode-extension-6f6ee9793f46">bait-and-switch</a>. After developers integrated it into their workflows, they moved the ability to save requests to local Git repositories behind a paywall. This wasn’t just a business decision – it was just one more betrayal of the developer community that had helped them grow. And working on VS Code extensions is a pain in the ass.</p>

<h2 id="the-performance-crisis-why-these-tools-feel-like-running-through-mud">The Performance Crisis: why these tools feel like running through mud</h2>

<p>Setting aside the ethical debates, performance is the main massive practical issue. The promise of Electron’s “write once, run anywhere” has turned into “runs poorly everywhere”. Postman takes 10+ seconds to launch and load on my MacBook M1 Pro. It eats gigabytes of RAM just to send a simple GET request, and it becomes <a href="https://community.postman.com/t/unusable-high-cpu-usage-is-anyone-listening-postman-version-7-18-1/10921">worse</a> <a href="https://github.com/postmanlabs/postman-app-support/issues/11976">over</a> the <a href="https://community.postman.com/t/postman-application-extremely-slow-or-unresponsive-after-recent-update-10-13-5/47042">years</a>. That’s horrible for something that is even simpler than an IDE.</p>

<p>The bloat isn’t just in the RAM; it’s in the UI. Postman has mutated into a platform trying to be everything at once – an API repo, a social network, a mock server, testing framework. <a href="https://stateofapis.com/2021/section/testing">Ninety percent of developers</a> just want to ping an endpoint and see the JSON. Instead, we’re dodging pop-ups and menus designed for enterprise sales teams and then just being locked out behind sign-up wall or paywall.</p>

<h2 id="evaluating-modern-alternatives">Evaluating modern alternatives</h2>

<p>This friction brought the community toward tools that value simplicity and, more importantly – Git workflows. Bruno is the name coming up most often. It’s open source and stores collections as plain-text files on your drive, which means I can version-control my API tests right alongside the source code in the same repo (unbelievable, right?)</p>

<p>It’s far from perfect, Bruno’s UI lacks polish, and migrating is a headache – scripts often break because the JavaScript sandbox isn’t the same as Postman’s. It also lacks some heavy-hitting enterprise features, such as advanced proxy support. But it’s promising to respect you – the user. <a href="https://biggo.com/news/202502011312_api-client-wars-lightweight-alternatives">At least for now.</a></p>

<h2 id="what-the-ideal-api-tool-would-look-like">What the Ideal API Tool Would Look Like</h2>

<ul>
  <li>Local-first, file-system centric. Collections and requests should be stored directly in the project repository.</li>
  <li>Import support for OpenAPI specs and GraphQL schemas, and straightforward test support.</li>
  <li>Zero login wall. The tool functions completely offline without forced account creation or mandatory cloud synchronization.</li>
  <li>Git-Native Collaboration. Collaboration happens through standard VCSs rather than paid “seat” licenses or proprietary cloud syncs.</li>
  <li>Native Performance. Built with high-performance languages (e.g., Rust) rather than web wrappers. Open instantly, consume minimal resources.</li>
  <li>Extensible Design. A modular plugin architecture that adds functionality and not bloating the core application.</li>
  <li>Universal Imports. Native support for importing OpenAPI specs, GraphQL schemas, Postman collections.</li>
  <li>Proxy Agnosticism. Tool must be designed to proxy traffic through any interception tool. Proxy-aware or browser-based architecture is must have.</li>
  <li>Scripting &amp; Auth flows. Pre-request&amp; post-response hooks.</li>
  <li>Straightforward testing. Built-in support for writing and running tests against API responses, by code.</li>
</ul>

<h2 id="and-whats-next">And what’s next?</h2>

<p>API tooling today sits somewhere between bloated, cloud-locked giants and lightweight, open, local-first newcomers. For every Postman or Insomnia, there’s a Bruno, Hurl, or Httpie — each being different points on the spectrum, but no single tool nails everything. Some are too barebones, some still need polish, and everywhere I look, it feels like there’s a missing piece.</p>

<p>But maybe that’s good. Maybe we’re still waiting for someone to finally break the compromise. I hope someone is working on it. Maybe it’s you. Maybe it’ll be me. The best tool probably hasn’t been built yet.</p>

<hr />

<p><strong>Update — March 2026:</strong></p>

<p>Well, well. Postman just shipped what they call <a href="https://blog.postman.com/new-postman-is-here/">Native Git</a> — collections stored as YAML files on your filesystem, branching that matches your actual Git branches, offline mode, the works. Sound familiar? It’s basically the Bruno pitch, repackaged inside a <a href="https://blog.postman.com/new-capabilities-march-2026/">$19/user/month paywall</a>. They even killed free team plans entirely — the Free tier is now solo-only, so if your team of three was happily collaborating on Postman for zero dollars, congratulations, that’s <a href="https://apidog.com/blog/postman-old-pricing-vs-new-pricing/">$684 a year now</a>. Collaboration went from “free feature” to “metered resource” overnight.</p>

<p>Here’s the thing that bugs me: the “recommended workflow” is still <code class="language-plaintext highlighter-rouge">postman workspace push</code> to sync everything back to their cloud. There’s a “local view” and a “cloud view,” and guess which one matters for sharing, governance, and all the enterprise features they actually want to sell you? The cloud one. So yes, your files technically live on disk now — right until you need to do anything collaborative, at which point you’re right back in Postman’s cloud, paying per seat. They saw the exodus toward local-first tools, copied the surface-level feature, and bolted it onto the same cloud-locked business model. It’s the API tooling equivalent of painting a racing stripe on a minivan. The direction is right, I guess, but the incentives haven’t changed.</p>]]></content><author><name>efpasia</name></author><category term="thoughts" /><summary type="html"><![CDATA[I’ve been a Postman user for my entire developer career. I remember when it was just a simple Chrome extension that made pentesting APIs slightly less painful. Those were simpler times. Today, I find myself joining the growing exodus of developers abandoning these tools because they sell out.]]></summary></entry></feed>